ASE is easy to start for beginners because when you install CrySPY, ASE is also automatically installed.
Although not highly accurate, ASE provides very lightweight and fast interatomic potentials, making it suitable for testing on a laptop or other low-spec machines.
Preparation of Input Files
Follow one of the instructions below, then proceed to the section on running CrySPY.
ASE provides interfaces to different codes.
ASE also includes Pure Python EMT calculator, which is suitable for testing CrySPY because of its fast and easy structure optimization.
In this tutorial, we try to use CrySPY in your local PC (Mac or Linux).
The target system is Cu 8 atoms.
Assumption
Here, we assume the following conditions:
CrySPY 1.2.0 or later in your local PC
CrySPY job filename: job_cryspy
ase input filename: ase_in.py
Input Files
Move to your working directory, and copy the example files by one of the following methods.
In [basic] section, jobcmd = zsh can be changed to jobcmd = sh or jobcmd = bash in accordance with your environment.
CrySPY runs zsh job_cryspy as a background job internally.
[ASE] section is required when you use ASE.
You can name the following files whatever you want:
jobfile: job_cryspy
ase_python: ase_in.py
The other input variables are discussed later.
calc_in Directory
The job file and input files for ASE are prepared in this directory.
Job File
The name of the job file must match the value of jobfile in cryspy.in.
The example of job file (here, job_cryspy) is shown below.
#!/bin/sh

# ---------- ASE
python3 ase_in.py
You can specify the input (ase_in.py) file names,
but it must match the values of ase_python in cryspy.in.
You must add sed -i -e ‘3 s/^.*$/done/’ stat_job at the end of the file in CrySPY.
Starting from version 1.4.2, CrySPY automatically appends the following line to the end of the job file. (See also: Features > Job file auto-rewriting)
# ---------- CrySPY
sed -i -e '3s/^sub.*/done/' stat_job
Note
For versions older than 1.4.2, the last line of the job file must be written as sed -i -e '3s/^sub.*/done/' stat_job. If you use a job file with this sed command in version 1.4.2 or later, it will simply be executed twice, which does not cause any problems. The meaning of the above sed command is to change the part starting with “sub” in the third line of the file stat_job to “done”.
Tip
(Detail: Features > Job file auto-rewriting) In the job file of CrySPY, the string CrySPY_ID is automatically replaced with the structure ID.
When you use a job scheduler such as PBS and SLURM, it is useful to set the structure ID to the job name.
For example, in the PBS system, #PBS -N Si_CrySPY_ID in ID 10 is replaced with #PBS -N Si_10.
Note that starting with a number will result in an error.
You should add a prefix like Si_.
Input for ASE
Input files corresponding to the number of stages (nstage in cryspy.in) are required.
Prepare the input file names by adding x_ as a prefix or _x as a suffix, where x is the stage number.
CrySPY searches for input files in the following order of priority:
x_ase_in.py
ase_in.py_x
ase_in.py
If you use the same input for all stages, you can omit x_ or _x.
In this ASE tutorial, since nstage = 1 is used, only one ASE input file, ase_in.py, is needed. You can omit x_ or _x.
An example of ase_in.py is shown below (for details on how to use ASE, refer to the official documentation).
from ase.constraints import FixSymmetry
from ase.filters import FrechetCellFilter
from ase.calculators.emt import EMT
from ase.optimize import BFGS
from ase.io import read, write
# ---------- input structure# CrySPY outputs 'POSCAR' as an input file in work/xxxxxx directoryatoms = read('POSCAR', format='vasp')
# ---------- setting and runatoms.calc = EMT()
atoms.set_constraint([FixSymmetry(atoms)])
cell_filter = FrechetCellFilter(atoms, hydrostatic_strain=False)
opt = BFGS(cell_filter)
# ---------- runconverged = opt.run(fmax=0.01, steps=2000)
# ---------- rule in ASE interface# output file for energy: 'log.tote' in eV/cell# CrySPY reads the last line of 'log.tote' file# outimized structure: 'CONTCAR' file in vasp format# check_opt: 'out_check_opt' file ('done' or 'not yet')# CrySPY reads the last line of 'out_check_opt' file# ------ energye = cell_filter.atoms.get_total_energy() # eV/cellwith open('log.tote', mode='w') as f:
f.write(str(e))
# ------ strucopt_atoms = cell_filter.atoms.copy()
opt_atoms.set_constraint(None) # remove constraint for pymatgenwrite('CONTCAR', opt_atoms, format='vasp', direct=True)
# ------ check_optwith open('out_check_opt', mode='w') as f:
if converged:
f.write('done\n')
else:
f.write('not yet\n')
Unlike VASP and QE, the ASE input (python script) is more flexible.
CrySPY has three rules:
Energy is output in units of eV/cell to log.tote file. CrySPY reads the last line of it.
Optimized structure is output to CONTCAR file in the VASP format.
The result of the optimization convergence check should be written as either done or not_yet in a file named out_check_opt. CrySPY reads the last line of this file.
soiap is Structure Optimization with InterAtomic Potential.
It is suitable for testing CrySPY because of its fast structure optimization.
See instructions to install soiap.
In this tutorial, we try to use CrySPY in your local PC (Mac or Linux).
The target system is Si 8 atoms.
Assumption
Here, we assume the following conditions:
(only version 0.10.3 or earlier) CrySPY main script: ~/CrySPY_root/CrySPY-0.9.0/cryspy.py
In [basic] section, jobcmd = zsh can be changed to jobcmd = sh or jobcmd = bash in accordance with your environment.
CrySPY runs zsh job_cryspy as a background job internally.
[soiap] section is required when you use soiap.
You can name the following files whatever you want:
jobfile
soiap_infile
soiap_outfile
soiap_cif
The other input variables are discussed later.
calc_in Directory
The job file and input files for soiap are prepared in this directory.
Job File
The name of the job file must match the value of jobfile in cryspy.in.
The example of job file (here, job_cryspy) is shown below.
Change /path/to/soiap into right path suitable for your environment.
You can specify the input (soiap.in) and output (soiap.out) file names,
but they must match the values of soiap_infile and soiap_outfile in cryspy.in.
The job file is written in the same way as the one you usually use except for the last line.
You must add sed -i -e '3 s/^.*$/done/' stat_job at the end of the file in CrySPY.
Note
sed -i -e '3 s/^.*$/done/' stat_job is required at the end of the job file.
Tip
In the job file of CrySPY, the string “CrySPY_ID” is automatically replaced with the structure ID.
When you use a job scheduler such as PBS and SLURM, it is useful to set the structure ID to the job name.
For example, in the PBS system, #PBS -N Si_CrySPY_ID in ID 10 is replaced with #PBS -N Si_10.
Note that starting with a number will result in an error.
You should add a prefix like Si_.
Input for soiap
Input files based on the number of stages (nstage in cryspy.in) are required.
Name the input file(s) with a suffix _x.
Here x means the stage number.
We are using nstage = 1, so we need only soiap.in_1.
soiap.in_1 is listed below.
crystal initial.cif ! CIF file for the initial structure
symmetry 1 ! 0: not symmetrize displacements of the atoms or 1: symmetrize

md_mode_cell 3 ! cell-relaxation method
               ! 0: FIRE, 2: quenched MD, or 3: RFC5
number_max_relax_cell 100 ! max. number of the cell relaxation
number_max_relax 1 ! max. number of the atom relaxation
max_displacement 0.1 ! max. displacement of atoms in Bohr

external_stress_v 0.0 0.0 0.0 ! external pressure in GPa

th_force 5d-5 ! convergence threshold for the force in Hartree a.u.
th_stress 5d-7 ! convergence threshold for the stress in Hartree a.u.

force_field 1 ! force field
              ! 1: Stillinger-Weber for Si, 2: Tsuneyuki potential for SiO2,
              ! 3: ZRL for Si-O-N-H, 4: ADP for Nd-Fe-B, 5: Jmatgen, or
              ! 6: Lennard-Jones
The input structure file is specified at the first line.
Use the same name as the value of soiap_cif in cryspy.in.
In this tutorial, we try to use CrySPY in a PC cluster with a job scheduler system such as PBS.
Here we employ VASP.
The target system is Na8Cl8, 16 atoms.
Assumption
Here, we assume the following conditions:
CrySPY 1.2.0 or later in your PC cluster
CrySPY job command: qsub
CrySPY job filename: job_cryspy
executable file, vasp_std in your PC cluster
Input Files
Move to your working directory, and copy the example files by one of the following methods.
In [basic] section, jobcmd = qsub can be changed in accordance with your environment.
CrySPY runs qsub job_cryspy as a background job internally in this setting.
You can name the following file whatever you want:
jobfile
We adopt a stage-based system for structure optimization calculations.
Here, we use nstage = 2.
For example, users can configure the following settings.
In the first stage, only the ionic positions are relaxed, fixing the cell shape, with low k-point grid density.
Next, the ionic positions and cell shape are fully relaxed with high accuracy in the second stage.
[VASP] section is required when you use VASP.
You have to specify k-point grid density (Å^-3) for each stage in kppvol.
Change VASPROOT to the appropriate path suitable for your environment.
The job file is written in the same way as the one you usually use except for the last line.
You must add sed -i -e ‘3 s/^.*$/done/’ stat_job at the end of the file in CrySPY.
Starting from version 1.4.2, CrySPY automatically appends the following line to the end of the job file. (See also: Features > Job file auto-rewriting)
# ---------- CrySPY
sed -i -e '3s/^sub.*/done/' stat_job
Note
For versions older than 1.4.2, the last line of the job file must be written as sed -i -e '3s/^sub.*/done/' stat_job. If you use a job file with this sed command in version 1.4.2 or later, it will simply be executed twice, which does not cause any problems. The meaning of the above sed command is to change the part starting with “sub” in the third line of the file stat_job to “done”.
Tip
(Detail: Features > Job file auto-rewriting) In the job file of CrySPY, the string CrySPY_ID is automatically replaced with the structure ID.
When you use a job scheduler such as PBS and SLURM, it is useful to set the structure ID to the job name.
For example, in the PBS system, #PBS -N Si_CrySPY_ID in ID 10 is replaced with #PBS -N Si_10.
Note that starting with a number will result in an error.
You should add a prefix like Si_.
Input for VASP
Input files corresponding to the number of stages (nstage in cryspy.in) are required.
Prepare the input file names by adding x_ as a prefix or _x as a suffix, where x is the stage number.
CrySPY searches for input files in the following order of priority:
x_INCAR
INCAR_x
INCAR
If you use the same input for all stages, you can omit x_ or _x.
We are using nstage = 2, so we need 1_INCAR_1 and 2_INCAR.
Here, 1_INCAR is set to fix the cell and relax only the ionic positions, while 2_INCAR is configured to fully relax both the cell and ionic positions.
CrySPY automatically generates POSCAR and KPOINTS files.
You have to prepare POTCAR file yourself.
The POTCAR included in this example file is empty, so please be aware of that.
Warning
POTCAR in this example is empty. We cannot distribute it.
In this tutorial, we try to use CrySPY in a machine with a job scheduler system such as PBS.
Here we employ QUANTUM ESPRESSO. (QE).
The target system is Si 8 atoms.
Assumption
Here, we assume the following conditions:
CrySPY job command: qsub
CrySPY job filename: job_cryspy
QE executable file: /usr/local/qe-6.5/bin/pw.x
QE input filename: pwscf.in
QE output filename: pwscf.out
Input Files
Move to your working directory, and copy input example files by one of the following methods.
In [basic] section, jobcmd = qsub can be changed in accordance with your environment.
CrySPY runs qsub job_cryspy as a background job internally in this setting.
We adopt a stage-based system for structure optimization calculations.
Here, we use nstage = 2.
For example, users can configure the following settings.
In the first stage, only the ionic positions are relaxed, fixing the cell shape, with low k-point grid density.
Next, the ionic positions and cell shape are fully relaxed with high accuracy in the second stage.
[QE] section is required when you use QE.
You have to specify k-point grid density (Å^-3) for each stage in kppvol.
Change /path/to/pw.x to the appropriate path suitable for your environment.
You can specify the input (pwscf.in) and output (pwscf.out) file names,
but they must match the values of qe_infile and qe_outfile in cryspy.in.
The job file is written in the same way as the one you usually use except for the last line.
You must add sed -i -e ‘3 s/^.*$/done/’ stat_job at the end of the file in CrySPY.
Starting from version 1.4.2, CrySPY automatically appends the following line to the end of the job file. (See also: Features > Job file auto-rewriting)
# ---------- CrySPY
sed -i -e '3s/^sub.*/done/' stat_job
Note
For versions older than 1.4.2, the last line of the job file must be written as sed -i -e '3s/^sub.*/done/' stat_job. If you use a job file with this sed command in version 1.4.2 or later, it will simply be executed twice, which does not cause any problems. The meaning of the above sed command is to change the part starting with “sub” in the third line of the file stat_job to “done”.
Tip
(Detail: Features > Job file auto-rewriting) In the job file of CrySPY, the string “CrySPY_ID” is automatically replaced with the structure ID.
When you use a job scheduler such as PBS and SLURM, it is useful to set the structure ID to the job name.
For example, in the PBS system, #PBS -N Si_CrySPY_ID in ID 10 is replaced with #PBS -N Si_10.
Note that starting with a number will result in an error.
You should add a prefix like Si_.
Input for QE
Input files corresponding to the number of stages (nstage in cryspy.in) are required.
Prepare the input file names by adding x_ as a prefix or _x as a suffix, where x is the stage number.
CrySPY searches for input files in the following order of priority:
x_pwscf.in
pwscf.in_x
pwscf.in
We are using nstage = 2, so we need 1_pwscf.in and 2_pwscf.in.
Here, 1_pwscf.in is set to fix the cell and relax only the ionic positions, while 2_pwscf.in is configured to fully relax both the cell and ionic positions.
Change pseudo_dir to your suitable directory.
Inputs for structure data and k-point such as ATOMIC_POSITIONS and K_POINTS are automatically appended by CrySPY with pymatgen.
Users do not have to prepare them in x_pwscf.in.
calc_code: Structure optimizer. Choose from VASP, QE, OMX, soiap, LAMMPS, ASE
tot_struc: The total number of structures. In this case, 5 random structures are generated at 1st run.
nstage: The number of stages. It’s up to you.
njob: The number of jobs running at the same time. In this example, CrySPY sets 2 slots for structure optimization, in other words, optimizes every 2 structures.
jobcmd: Command for jobs. Use bash, zsh, qsub, and so on.
jobfile: File name of the job file.
[structure] Section
atype: Atom type. e.g. for Na8Cl8: atype = Na Cl.
nat: The number of atoms corresponding to each atype. e.g. for Na8Cl8: nat = 8 8
Script to Run
Note
For version 1.0.0 or later, skip this page. The executable script is automatically installed.
Assumption
Here, we assume the following condition:
CrySPY main script: ~/CrySPY_root/CrySPY-0.9.0/cryspy.py
Make Script
Let’s make a convenient shell script to avoid typing long commands over and over again.
Here, we create the script, cryspy (any file name will do).
CrySPY continues the simulation if you have cryspy.stat file.
Tip
Continue if you have crypy.stat Start from the beginning if you don’t have cryspy.stat
Submit Job
Run CyrSPY again.
cryspy
Check the screen or log_cryspy file.
[2023-07-10 18:52:51,859][cryspy_restart][INFO]


Restart CrySPY 1.2.0


[2023-07-10 18:52:51,869][ctrl_job][INFO] # ---------- job status
[2023-07-10 18:52:51,904][ctrl_job][INFO] ID      0: submit job, Stage 1
[2023-07-10 18:52:51,931][ctrl_job][INFO] ID      1: submit job, Stage 1
And also cryspy.stat file.
...
(omit)
...
[status]
id_queueing = 2 3 4
id      0 = Stage 1
id      1 = Stage 1
CrySPY submitted two jobs for structure ID 0 and 1 as you set njob = 2 in cryspy.in.
Calculations are performed in the work directory.
These directory names correspond to their structure ID.
tree -d work
work
├── 000000
├── 000001
└── fin
When the two jobs are done, run CrySPY again.
cryspy
[2023-07-10 18:55:01,053][cryspy_restart][INFO]


Restart CrySPY 1.2.0


[2023-07-10 18:55:01,058][ctrl_job][INFO] # ---------- job status
[2023-07-10 18:55:01,058][ctrl_job][INFO] ID      0: Stage 1 Done!
[2023-07-10 18:55:01,093][ctrl_job][INFO]     collect results: E = -0.00696997755502915 eV/atom
[2023-07-10 18:55:01,132][ctrl_job][INFO] ID      1: Stage 1 Done!
[2023-07-10 18:55:01,133][ctrl_job][INFO]     collect results: E = 0.4934076667166454 eV/atom
[2023-07-10 18:55:01,144][cryspy][INFO]

recheck 1

[2023-07-10 18:55:01,145][ctrl_job][INFO] # ---------- job status
[2023-07-10 18:55:01,153][ctrl_job][INFO] ID      2: submit job, Stage 1
[2023-07-10 18:55:01,161][ctrl_job][INFO] ID      3: submit job, Stage 1
If you set nstage = 2 (more than 2), new jobs on stage 2 for ID 0 and 1 are submitted.
If you set nstage = 1, CrySPY collects calculation data of ID 0 and 1, then submits next ID’s jobs.
Directories of the finished structure are moved to the fin directory.
Repeat cryspy several times until all 5 structures are done.
You can delete the work directory when the simulation is done if you do not need it.
Move to data directory. There should be a few more files.
$ cd data
$ ls
cryspy_rslt  cryspy_rslt_energy_asc  init_POSCARS  opt_POSCARS  pkl_data/
cryspy_rslt: Result file.
cryspy_rslt_energy_asc: Result file sorted in energy ascending order.
init_POSCARS: Initial struture file in POSCAR format.
opt_POSCARS: Optimized structure file in POSCAR format.
pkl_data/: Directory to save pickled data.
The results are written to text files, cryspy_rslt and cryspy_rslt_energy_asc (and also saved in pickle data in pkl_data directory).
From v1.5.0, rslt_out in the [option] section controls when cryspy_rslt and cryspy_rslt_energy_asc are written. The default is always. See Input File > [option] Section for details.
Each result appends to cryspy_rslt file in the order in which one finished earlier.
cat cryspy_rslt
   Spg_num Spg_sym  Spg_num_opt Spg_sym_opt  E_eV_atom  Magmom      Opt
0      139  I4/mmm          139      I4/mmm  -3.000850     NaN     done
1       98  I4_122           12        C2/m  -3.978441     NaN  not_yet
2       16    P222           16        P222  -3.348616     NaN  not_yet
3       36  Cmc2_1           36      Cmc2_1  -3.520306     NaN  not_yet
4       36  Cmc2_1            4        P2_1  -3.304168     NaN  not_yet
Info
Not ID order in cryspy_rslt
In cryspy_rslt_energy_asc file, the results are sorted in energy ascending order.
cat cryspy_rslt_energy_asc
   Spg_num Spg_sym  Spg_num_opt Spg_sym_opt  E_eV_atom  Magmom      Opt
1       98  I4_122           12        C2/m  -3.978441     NaN  not_yet
3       36  Cmc2_1           36      Cmc2_1  -3.520306     NaN  not_yet
2       16    P222           16        P222  -3.348616     NaN  not_yet
4       36  Cmc2_1            4        P2_1  -3.304168     NaN  not_yet
0      139  I4/mmm          139      I4/mmm  -3.000850     NaN     done
Spg_num and Spg_sym show space group information on initial structures.
Spg_num_opt and Spg_sym_opt are those of optimized structures.
The last column Opt indicates whether or not optimization reached required accuracy.
Append Structures
Last updated: October 16, 2026
Of course only 5 structures are not enough to find stable structures.
You can append structures whenever you want.
Here let’s append more 5 structures.
For Si-Si mindist, the default value of 1.11 Å is used in the first structure generation (see log_cryspy), which is a little too close.
Let us try to set the mindist to 2.0 Å.
...
(omit)
...

2023/03/19 00:01:47
CrySPY 1.0.0
Restart cryspy.py


Changed tot_struc from 5 to 10
Changed mindist from None to [[2.0]]

Backup data

# ---------- Append structures
# ------ mindist
Si - Si 2.0
Structure ID      5 was generated. Space group: 218 --> 221 Pm-3m
Structure ID      6 was generated. Space group:  86 --> 129 P4/nmm
Structure ID      7 was generated. Space group: 129 --> 129 P4/nmm
Structure ID      8 was generated. Space group: 191 --> 191 P6/mmm
Structure ID      9 was generated. Space group:  31 -->  31 Pmn2_1
Remember that CrySPY goes into structure generation mode whenever you change the value of tot_struc.
In this mode, CrySPY does not do any other action such as collecting data, submitting jobs, and so on.
Note
Structure generation mode whenever you change the value of tot_struc. From version 1.0.0, CrySPY automatically backs up when adding structures.
See features/backup.
Repeat cryspy & several times until all appended structures are done.
The auto script (repeat_cryspy) may help you.
Analysis and Visualization
Last updated: February 9, 2026
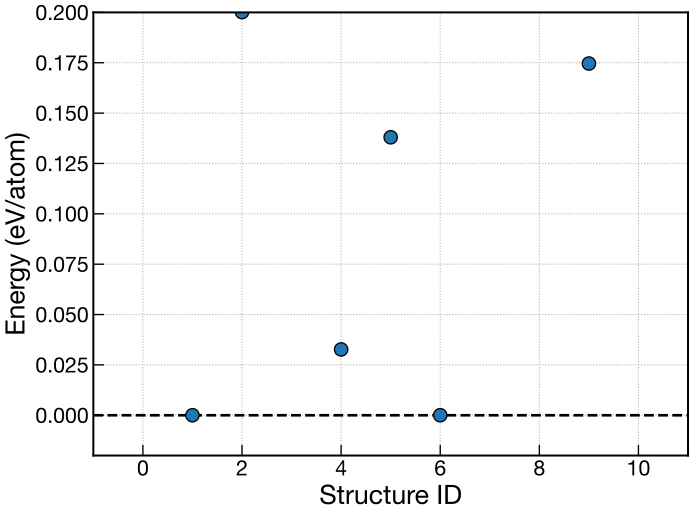
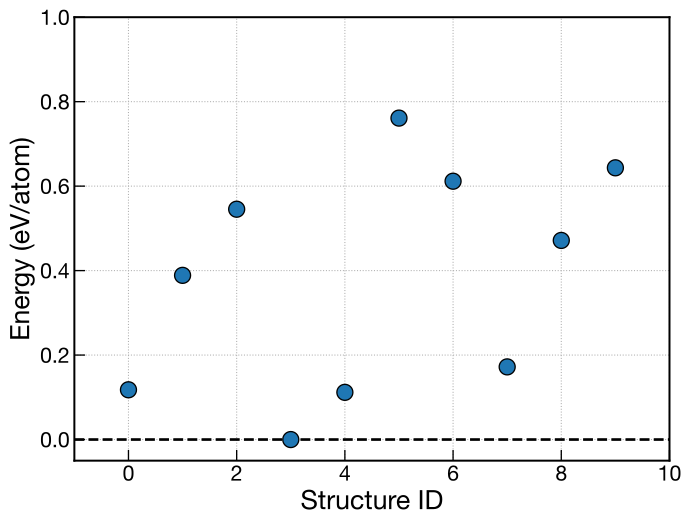
Energy Plot
Since version 1.4.4, results can be easily visualized using the cryspy-Eplot command as follows:
cryspy-Eplot
The file is saved to ./data/energy_plot/energy_RS_{tot_struc}.{fig_fotmat}.
For more advanced data analysis or figure customization, download the files and use Jupyter Notebook as shown below.
Download Data
It is assumed here that you analyze and visualize CrySPY data on your local PC.
If you use CrySPY on a supercomputer or workstation, download the data to your local machine.
You can delete the work and backup directories if they are not needed, as their file size can be very large.
Jupyter Notebook
Move to the data/ directory in the results you downloaded earlier.
Then, if the CrySPY utility has already been downloaded locally, copy cryspy_analyzer_RS.ipynb.
Alternatively, you can download it directly from GitHub (CrySPY_utility/notebook/).
Launch Jupyter (e.g., VS Code, Jupyter Lab, or Jupyter Notebook),
and simply run the cells in order to obtain a figure like the one shown below.